🌻 1
Showing all public posts on this server. Log in to post and see your home timeline.
日本人如此热爱打扮,妆发水平也很高,但却能把公主们打扮成那样,属实难以理解。甚至日本皇族穿和服看起来都很局促,总不能是便宜货吧……
 寒江在下雪 (@hanchan@ckpt.hanchan.vip)
想到身边总有些讲不清需求的大人,如今赶时髦用上了豆包,被 AI 糊弄了,反倒觉得是自己表达不清,甚至当成笑话讲。可同样的人,在没有 AI 的年代,遇到听不懂自己胡言乱语的真人,却总能理直气壮地责怪对方。一想到未来人们对机器的宽容,竟可能远胜于对真实的人的善意,我就会感到恐惧
ckpt.hanchan.vip
 1
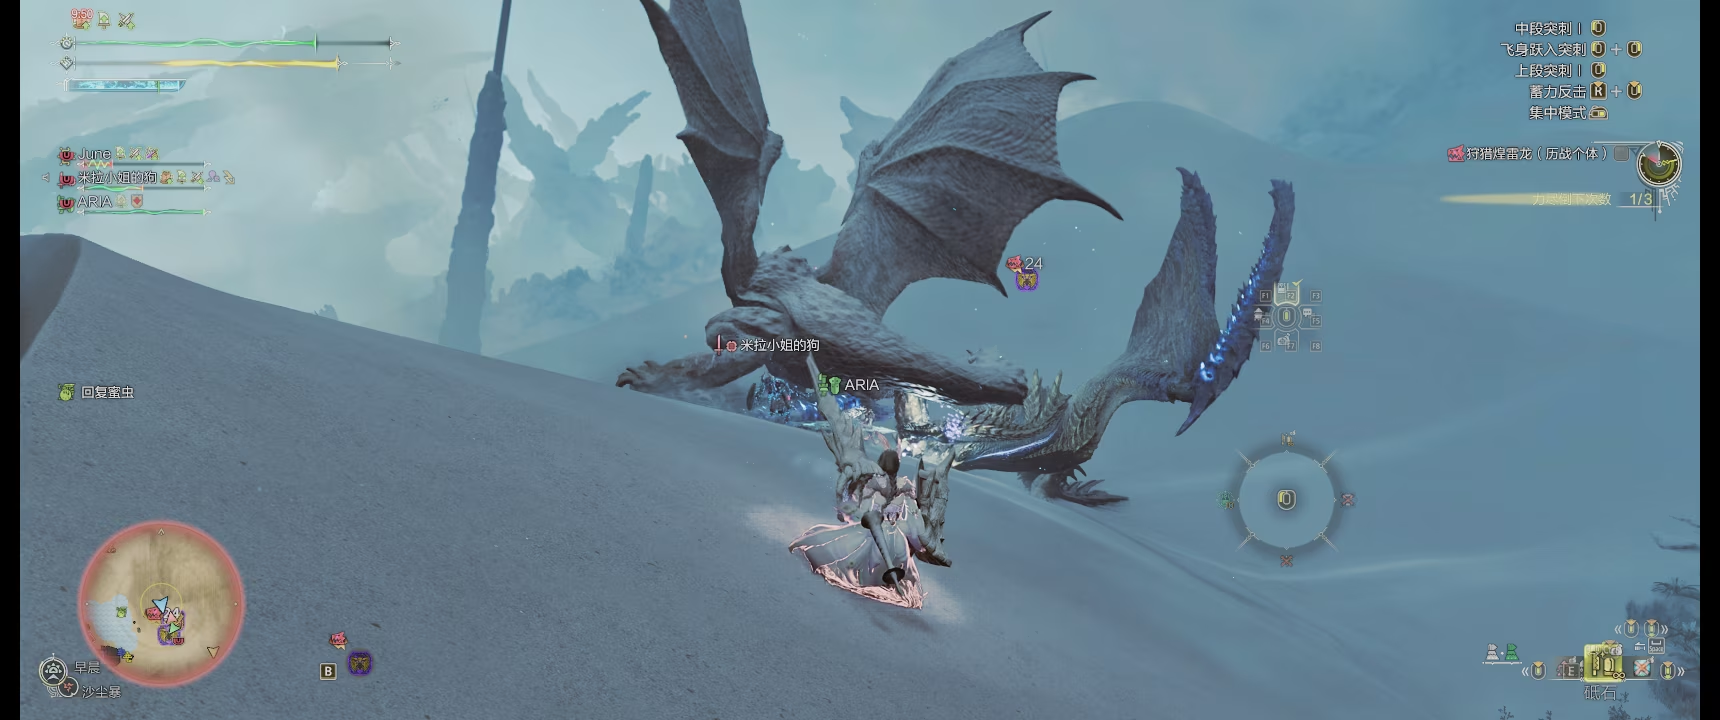
神仙打架,一群猴子在帮边凑热闹~ #MHWild
@gttnnn 字面上看起来不就是叶公好龙然后画龙点睛吗!
老天,我一直把叶公好龙当成画龙点睛理解了,今日才发觉不是一个故事 
@sogood 阿莫林有能名帅!
@timbray Worse things happen at sea
@IanOB oops
So, check out this useful “Compare Mac Models” page (h/t @gruber). Scroll down to the “Compute” and compare the stats. Go on, do it, I’ll wait. See anything that makes you go WTF?!? I did.
2/ It’s the Memory Bandwidth numbers, “Up to 170 GB/s” for the M6, “Up to 614 GB/sec” for the M5 Max/Pro models. This is a big deal? Computers pull data from memory into the CPU, crunch it, write it back out. But they can crunch many times faster than the memory can deliver it. So the effective performance depends a *lot* on memory bandwidth.
3/ The kind of heavy-duty work these things are designed for (LLMs, big-video, etc) all tend to work with huge blobs of data, so in many cases the memory bandwidth is the limiting factor. Old programmer mantra: “All computers wait for data at the same speed.”
@timbray the M6 is inferior in almost everything, but it's also half the price of the M5 Max...
I think the 6 stands for "2026"
@johnefrancis Huh… I'd have thought the performance increased as the number after the “M” did.
一只白切鸡,不带腿的上庄30块,带腿的下庄50块。喂拜托,一只鸡怎么能差那么多。。。 
@Tuzio or just run Doom on the company network like back in the 90s.